AI has caused incredible productivity gains for software developers. A developer can now integrate generative AI-based coding assistants into an integrated development environment (IDE), talk to these assistants, and have them write and review code, write unit tests, and create data relevant to those tests. GitHub reports that participants using AI assistants completed a specific coding task 55% faster than those who didn't use assistants.[1]
These productivity gains have a major implication: It's now necessary to test software earlier in the software development life cycle (SDLC). One industry analysis found that organizations with higher AI adoption produced pull requests that were 18.2% larger, suggesting that AI-assisted development may increase the amount of code that requires review and validation.[2] To fully benefit from AI capabilities, many in the industry are recommending shift-left testing, especially for regression testing, functional end-to-end and integration testing, and in some cases even performance testing.[3],[4] The cost of deferring these tests can be very high.
| Testing activity | Dependence on production-like data | Nature of the dependency |
|---|---|---|
| Static analysis and code review | None or minimal | Examines code without executing application workflows |
| Unit testing | Low to moderate | Requires controlled inputs, fixtures, mocks and expected outputs |
| Component and API testing | Moderate | Requires valid payloads, states and response combinations |
| Integration testing | High | Requires coordinated data across services, tables and systems |
| Functional and end-to-end testing | Very high | Requires application-valid users, accounts, transactions and workflow states |
| Regression testing | Very high | Requires repeatable datasets covering existing behavior |
| Boundary and negative testing | Very high | Boundary values and deliberately invalid conditions; realistic out-of-distribution data points surrounding application state when testing complete workflows |
| Performance and load testing | Very high | Requires realistic volumes, distributions, relationships and transaction histories |
| User acceptance testing | Very high | Requires realistic business scenarios understandable to users |
These testing activities depend on different forms of test data. Most require realistic, production-like data that covers normal conditions, rare edge cases, valid boundary cases, realistic scenarios, and sufficient volumes for performance testing. Boundary and negative testing additionally require deliberately constructed conditions that may not exist in production. The table below summarizes how different testing activities depend on these forms of test data. Provisioning realistic test data has traditionally relied heavily on copying, subsetting, and masking production data before bringing it into lower environments. This creates a bottleneck since the data requests have to be approved; data is then masked and anonymized through processing, which can involve running a computationally intensive ETL pipeline, slowing things down further. Industry vendors consistently report that test-data provisioning can take days or weeks.[5]According to a 2026 Perforce Delphix survey of 518 enterprise leaders, 99% of respondents waited longer than one business day for a fresh production copy of test data, while 42% waited weeks or months.[6]
Increasingly, AI-generated synthetic test data is being recognized as a powerful and scalable technique for creating this necessary test data early in the software development life cycle. However, there is confusion about whether AI has the ability to generate test data that is as realistic as the production data and that will satisfy the requirements for various testing activities listed in the table above.
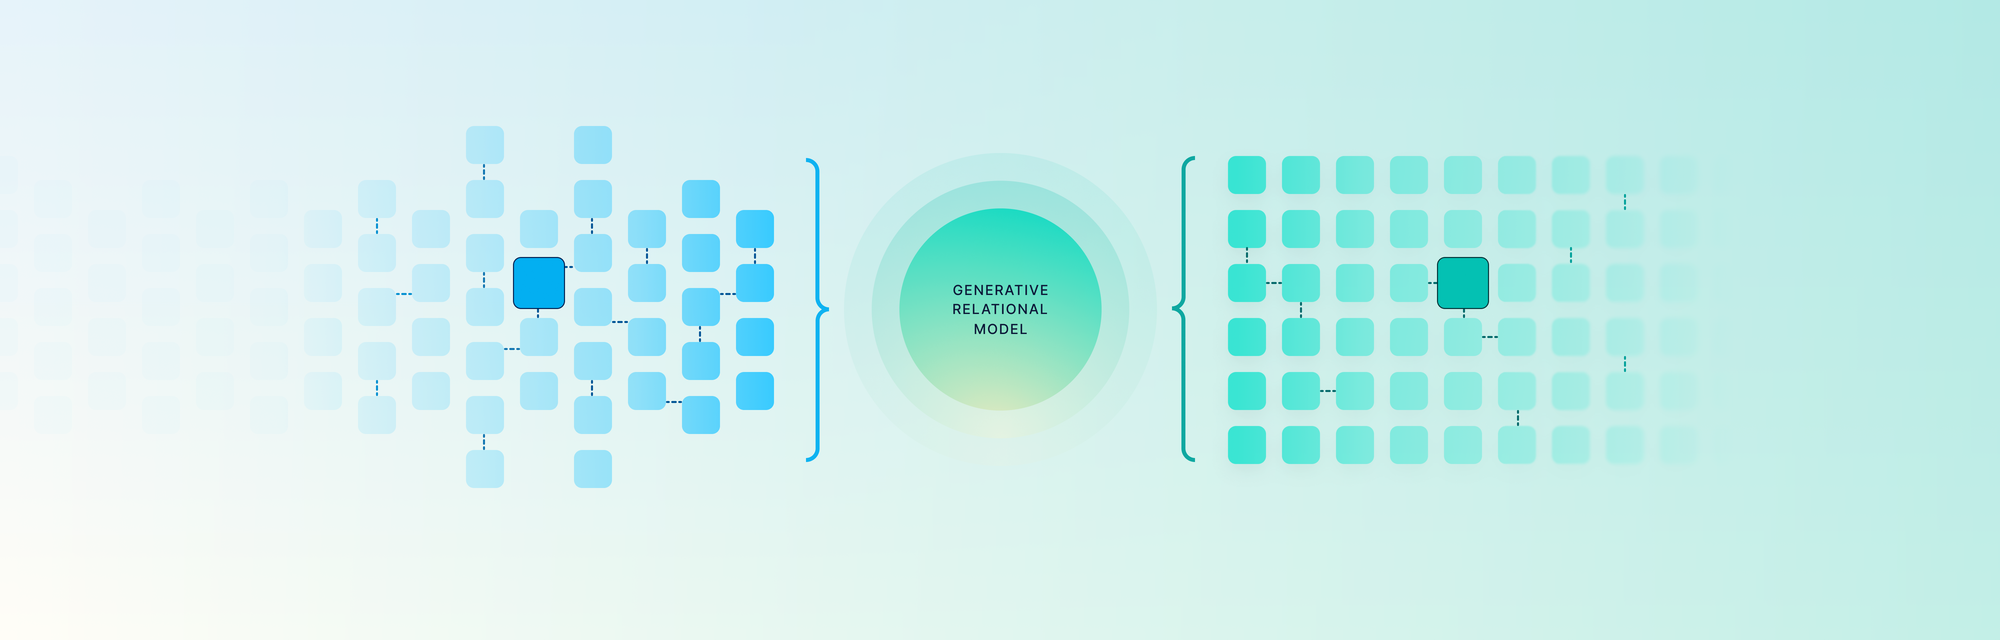
Over the past few years, we have worked closely with enterprises as they trained generative relational models, generated synthetic data, and provisioned that data into lower environments. Through these deployments, we have learned what AI-generated test data must provide to support enterprise application testing.
What is AI-generated synthetic test data?
AI-generated synthetic test data has the following characteristics:
-
AI-generated: The data is produced by a trained AI model. This model is a generative relational model that learns from a subset of production data and metadata and can incorporate business rules and testing requirements.
-
Synthetic: The generated records are new. They are not copied, subsetted, or masked versions of production records.
-
Test data: The data is generated specifically for software application testing, including component, integration, functional, end-to-end, regression, boundary, negative, and performance testing.
For brevity, this article refers to AI-generated synthetic test data as AI-generated test data.
To create AI-generated test data:
-
Download and install training software. It is typically a software development kit (SDK) .
-
Point it to a set of exported (seed or training) data files from a database, or a database with a small subset of your production data. (In the next article, we will share several methods for pulling together this data.)
-
Use the SDK's API to train a model, and save the model file. This is your generative relational model.
-
Once you have trained a model, you can deploy it in your environment and use it to generate synthetic test data.
Foundational requirements for enterprise deployment
Even before its data quality and testing capabilities are evaluated, an AI-generated test data approach must satisfy several foundational requirements in order to be deployed in enterprise. If these requirements are not met, any more advanced capabilities have limited practical value. When evaluating an approach, start with this checklist:
The model must be trained from scratch in your environment, using your data. General-purpose, pretrained generative models are not designed to learn and reproduce complex relational databases. Adapting them can require extensive fine-tuning and may still produce invalid data, making them expensive and inefficient for test data generation.
Training should also take place entirely within your environment. Sending proprietary data to an API-based generative AI service introduces security and governance concerns, as well as ongoing costs for fine-tuning and generation. A model trained from scratch on your enterprise data remains within your environment and is purpose-built for generating effective test data, as we explain in the next section.
Data must never leave your environment. You should be able to train the model locally; thus, no data should ever leave your environment. Many enterprises hold this as a strict requirement, for reasons we explain here.
Training must be fast and cost-effective. To match the speed of software creation, the ongoing flow of CI/CD, and the scale of new features and applications, model training must be fast and inexpensive. In our deployments, we have trained models for databases containing more than 60 tables in a few minutes to approximately one hour on CPU or GPU machines.
The model must be a single, lightweight, portable file. The model should be portable across environments without requiring extensive infrastructure, which is costly and effortful to maintain. An enterprise-ready model captures the high-level statistics, non-linear patterns, and relational structures within the data it's trained on, and the model's size is a function of these parameters, rather than reflecting the amount of the data. Because model size depends primarily on the learned parameters rather than the number of source records, the trained model can (and should) be substantially smaller than its training data.
You should be able to sample as much data as you want, on demand. The model must generate new records repeatedly and at user-specified volumes without requiring retraining.
In order to be useful, the model must learn and generate data that goes beyond statistical realism.
If these foundational requirements are satisfied, the approach has the foundation needed for enterprise deployment. The next question is whether it can generate test data that is useful for application testing. The next question is whether it can generate test data that is useful for application testing. To produce useful test data, the AI model must learn a number of properties in your data and generate synthetic data that emulates those properties which means the platform that trains the model must have these capabilities. To assess whether the platform and model truly have these capabilities, you can evaluate the synthetic data they generate. (Open-source tools such as SDMetrics can help evaluate whether generated data satisfies these requirements.)
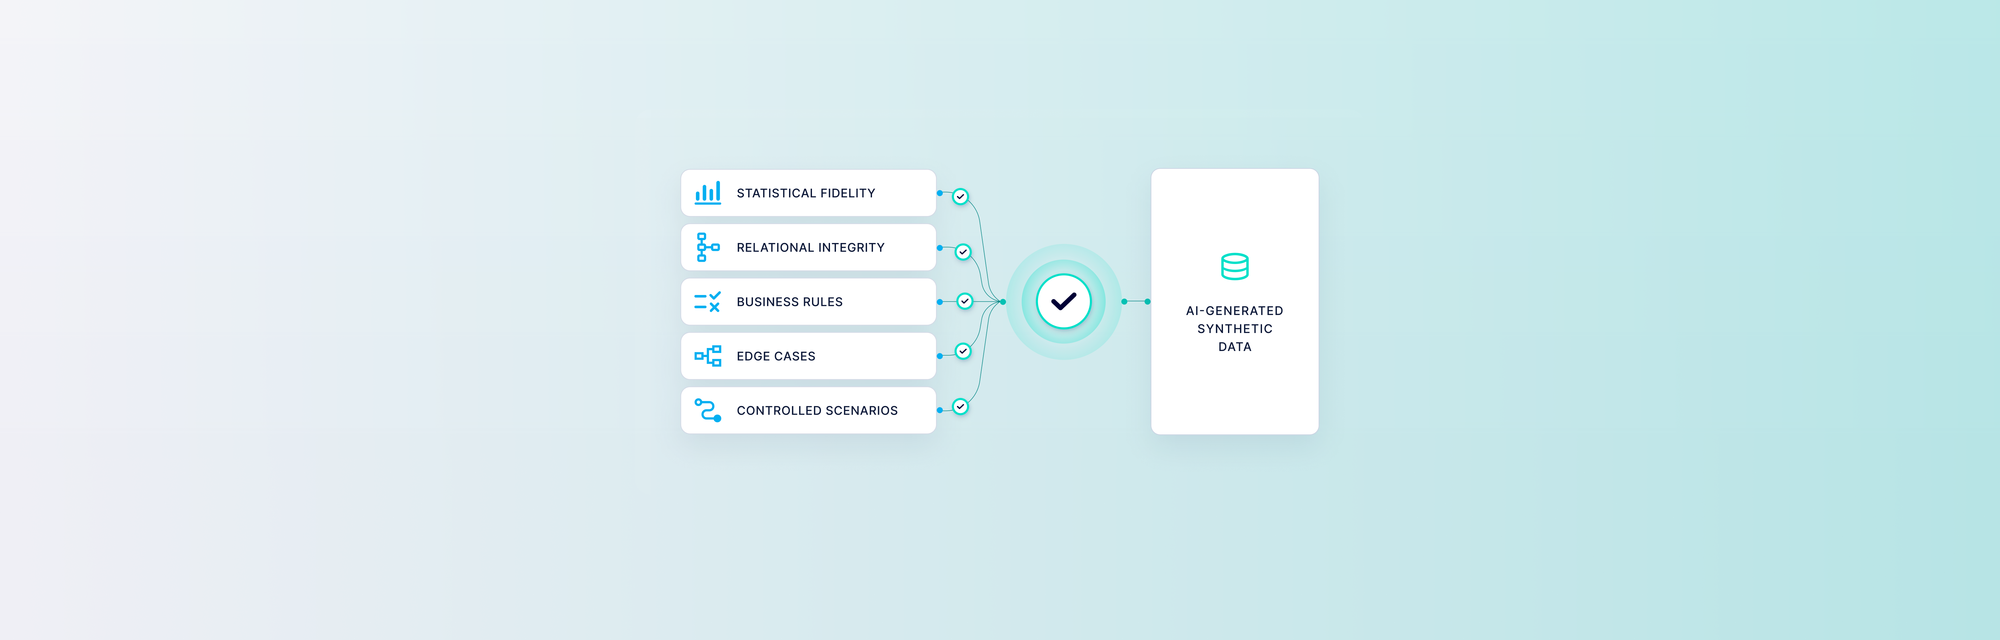
Here is a list of the critical capabilities these models must have, with in-depth descriptions below:
| Critical capability | Model must be able to |
|---|---|
| Statistical Fidelity Does the generated data statistically resemble the original data? | Generate data that preserves distributions, correlations, formats and other statistical properties of the source data. |
| Relational Integrity Preservation Does the generated database remain structurally coherent? | Generate data that maintains keys, cardinalities and dependencies across related tables and systems. |
| Business-Rule and Semantic Consistency Does the generated data obey the implicit and explicit rules of the application? | Generate data that preserves application logic, natural-key conventions, contextual dependencies and valid cross-field or cross-table combinations. |
| Edge-Case and Out-of-Distribution Generation Can the model generate the data needed to test conditions that are absent from the source data? | Create the boundary, invalid, rare and unobserved conditions required for broader test coverage. |
| Controlled Scenario Generation Can testers specify the situation they want to test and generate a complete, coherent database for it? | Produce data for specified populations, distributions, volumes and anticipated operating conditions. |
The five capabilities above determine whether the generated data is useful for testing. Privacy protection is a separate requirement that determines whether the model can be safely deployed.
Statistical fidelity
Models must generate data that preserves the patterns, correlations and distributions present within individual tables. A model that shows statistical fidelity captures correlations and dependencies between columns (both linear and nonlinear) and emulates them in the synthetic data. Statistical fidelity is the baseline capability provided by many synthetic data platforms. For applications that use a single table, this capability may be sufficient as long as the relevant distributions, correlations, and formats are preserved.
Models must be able to generate these patterns across a breadth of data types: A model must capture and generate patterns across a variety of data types, including GPS coordinates, phone numbers, etc. These data types may be common or specialized: For instance, we once worked with an automobile company that needed us to generate German VINs (vehicle identification numbers).
Relational fidelity and integrity preservation
Models must generate correlations, keys, relationships and cardinality across dozens to hundreds of tables. The enterprise applications and end-to-end workflows we have encountered commonly consume data fields from 10 to 100 related tables. Thus, a model must capture complex intertable relationships including: composite keys, polymorphic relationships, 1-1 relationships, and many others in addition to patterns, correlations and distributions. The model must produce relationally consistent data that maintains referential integrity.
Models on some platforms lack these important abilities. Such platforms instead combine data generation with ETL-based pipelines to copy and mask the production data, or else use rule-based generation or another technique. More advanced platforms allow you to train a model that captures the relevant structural and statistical properties of your data.
Some platforms create models that can capture these relationships for 3-5 tables only. Most of these also require in-depth preprocessing or setup, which is not scalable when working with the 10-100 tables typical of enterprise applications. In this article, we share some common preprocessing and setup requirements we have come across.
Business-rule and semantic consistency
Models must generate data consistent with business rules, conditional relationships, and hidden context, including rules that span multiple tables. The model must be able to learn observable business rules, accept explicitly provided rules, and enforce both when generating test data. Business rules are not the same as statistical patterns. Instead, they are the logical, deterministic rules that govern how certain columns behave. These rules can affect two columns, can span multiple columns across tables, or can be contained within a single column. Let's go through some examples:
Example 1: A savings account product is not available in certain regions
Imagine a bank that serves 30 regions, but does not offer a particular savings account product in 12 of these regions. For customers in those regions, that product cannot appear as their account type. This is a deterministic constraint based on a business rule. For example, if region == "Antwerp", then account_type cannot be "CYN".
Example 2: Membership and benefits
Rules can span multiple tables. Imagine a situation where only premium members of a service receive benefits. In this example, only someone with a premium membership will have an entry in the benefits table.
That context is not necessarily revealed anywhere in the schema. Instead, it is used by the application when it processes the data. A model must discover this rule in the data, model it, and follow it when synthesizing data for this database. Any synthetic member with a basic membership cannot have an entry in the benefits table because, by definition, that member does not have benefits.
Example 3: Logical rules buried within a column
An account ID such as DK-RETAIL-2026-00421 may encode a transaction's country, account type, year, and sequence. If a synthetic account record says the country is France, but the ID itself begins with DK (for Denmark), the database may remain relationally consistent while the application rejects it. While ID uniqueness and consistent ID usage across tables fall under the category of relational integrity preservation, preserving the internal meaning and format of the ID depends on the model having Business-Rule and Semantic Consistency.
All of these logical constraints are hidden. They may not be noted in the schema or in any other metadata. But because applications rely on the logic of these constraints in order to correctly process the data, all generated data must adhere to them. A generated database could have perfectly valid primary and foreign keys and still be unusable because it violates one or more of these implicit rules. Ensuring that synthetic data is actually application-valid prevents many spurious test failures during E2E, functional and regression testing.
Edge-case and out-of-distribution generation
Models must be able to generate boundary cases, invalid cases, and scenarios outside the range of the data used to train them. Imagine an insurance application that does not sell insurance to anyone under 15 years old. Its production data will not contain anyone under 15. In other words, there is no such data available for the model to learn from or sample.
But as one of our customers has put it, “the tester wants what the tester wants.” The tester might say, “Give me data for someone who is 14 years old, so I can test this condition.” Or they might say, “Give me data for someone who is 300 years old.” Obviously, that data does not exist in the production database either.
The 14-year-old and the 300-year-old serve different and valid testing purposes:
-
14 years old: A realistic boundary or negative case that the application is explicitly expected to reject.
-
300 years old: An extreme invalid input used to test validation, failure handling, and application resilience.
Even though a model cannot possibly have trained on similar data (as it does not exist), it should still be able to generate test data for these conditions on demand. In generative AI, we call this “out-of-distribution” data generation. It broadens test coverage by supplying specified boundary, negative, rare, and unobserved conditions that production data cannot provide.
Controlled scenario generation
Models must be able to generate controlled databases for specified scenarios, distributions, volumes, and anticipated future states. A model with this capability can create an entire test database for a specific scenario. It can also generate scenarios pertaining to different volume requirements. For instance:
Current volume: 5,000 payments per month
Future volume: 50,000 payments per month
Current distribution: 80% domestic currency and 20% foreign currency
Future distribution: 20% domestic and 80% foreign currency
A model should be able to generate test data that matches future scenarios.
Privacy-protected data generation
One reason test data takes so long to provision is that production data contains sensitive fields that must be protected before the data can be moved into lower environments. With AI-generated test data, the production data does not move. Instead, a trained generative relational model is deployed in the lower environment. This creates another important requirement:
Models must generate data that does not expose sensitive training data. Generative models can sometimes memorize rare records, or reproduce values from their training data. Even learned metadata, such as the exact minimum or maximum value of a column, can reveal sensitive information. Before a model is moved into a lower environment, it must therefore be assessed for memorization and other forms of privacy leakage. When a formal privacy guarantee is required, it must be provided through a mechanism such as differential privacy; privacy cannot be assumed simply because the model generates new records. Unfortunately, many models fail one or more of these conditions (see our previous article, “7 signs a synthetic data software violates privacy" ).
Cross-cutting requirements for platforms
On top of these critical capabilities, platforms must meet additional cross-cutting requirements that enable this new, faster way of data provisioning. Advanced platforms must:
Have automated model training capabilities without needing excessive manual work. A platform may theoretically support relational modeling or business rules, but if handling these things requires extensive manual configuration, that platform will not be practical at an enterprise scale.
Support reproducibility and versioning: Platforms should support reproducible generation from versioned models, configurations, and parameters. This reduces the need to store and maintain numerous static datasets while allowing teams to recreate test conditions when needed.
Achieve fast, large-scale sampling performance: High sampling performance is critical for generating a large volume of data for performance testing and for generating regression data on demand.
Include privacy and memorization assessments: Platforms must have the ability to assess and quantify the risk that models have memorized training data.
Undergo quality and diagnostic assessments prior to deployment. The platform must have the ability to ensure the model meets all the critical capabilities mentioned previously. This requirement can be satisfied using a number of relevant assessment measures SDMetrics, which is open source.
Summary
| Testing activity | Statistical fidelity | Relational integrity | Business-rule and semantic consistency | Edge-case and out-of-distribution generation | Controlled scenario generation |
|---|---|---|---|---|---|
| Component and API testing | ● | ○ | ○ | ○ | ○ |
| Database-backed application testing | ● | ● | ○ | ○ | |
| Integration testing | ● | ● | ● | ○ | ○ |
| Functional and end-to-end testing | ● | ● | ● | ○ | ● |
| Regression testing | ● | ● | ● | ○ | ● |
| Boundary and negative testing | ● | ○ | ○ | ● | ● |
| Performance and load testing | ● | ● | ○ | ● | |
| Future-state testing | ● | ● | ● | ○ | ● |
| User acceptance testing | ● | ● | ● | ● |
AI-assisted coding did not create the need for shift-left testing, but it has made that need substantially more urgent. Faster and broader code changes increase the value of running regression, integration, functional, and selected performance tests earlier in the development lifecycle. Doing so requires test data that can be provisioned quickly and that preserves the statistical, relational, and semantic properties required by each test.
Generative relational models are AI models trained on enterprise-specific databases. They offer a promising way to provide that data, but only when the model and its supporting platform possess the capabilities described in this article. Over the last four years, we have learned a great deal about what an AI model must be able to do to support application testing. As it turns out, generating statistically realistic data is only the start.
Eirini Kalliamvakou, “Research: Quantifying GitHub Copilot’s Impact on Developer Productivity and Happiness,” GitHub Blog, September 7, 2022, updated May 21, 2024, https://github.blog/news-insights/research/research-quantifying-github-copilots-impact-on-developer-productivity-and-happiness/ ↩︎
Nicholas Arcolano, “Better Code, or Just Bigger? AI-Assisted Pull Requests Are 18% Larger,” Jellyfish, September 2, 2025, https://jellyfish.co/blog/ai-assisted-pull-requests-are-18-larger/. ↩︎
Luke Mahon, “AI Is Writing Your Code. Is Your Regression Testing Keeping Up?,” Tricentis, April 28, 2026, https://www.tricentis.com/blog/intent-drift-ai-code-fix-regression-blind-spots. ↩︎
Diego Lo Giudice and Bill Seguin, “It’s Time for Shift-Left Performance Testing,” Forrester, April 19, 2019, https://www.forrester.com/blogs/its-time-for-shift-left-performance-testing/. ↩︎
Broadcom, “Test Data Management,” accessed September 2, 2026, https://docs.broadcom.com/docs/test-data-management ↩︎
Jensen, Aaron, Woody Evans, and Matthew Yeh. “The 2026 Test Data Management Report for AI-Ready Enterprises.” Perforce Software, June 16, 2026. ↩︎