Generative AI models have transformed the way we create and work with language, software, images, and video. But what about enterprise relational data—data produced by the interactions between businesses and their customers. How do we build generative models that understand and preserve the important parts of this data, statistical patterns, data structure, relationships, context, and business rules embedded in the data and spanning its tables?
Most foundation models—including those for language, images, video, UI/UX designs, and software code—are trained on massive amounts of relevant data. But enterprise relational data is not available at the scale required for such training. There is no publicly available enterprise data; instead, this data is proprietary to specific enterprises, which gather it over the course of decades and use it to make business decisions, build and improve software applications, and differentiate themselves from their competitors. Because enterprise relational data is rich in schemas, relationships, business rules, context, and data distributions, working with it also requires a fundamentally different approach to generative AI.
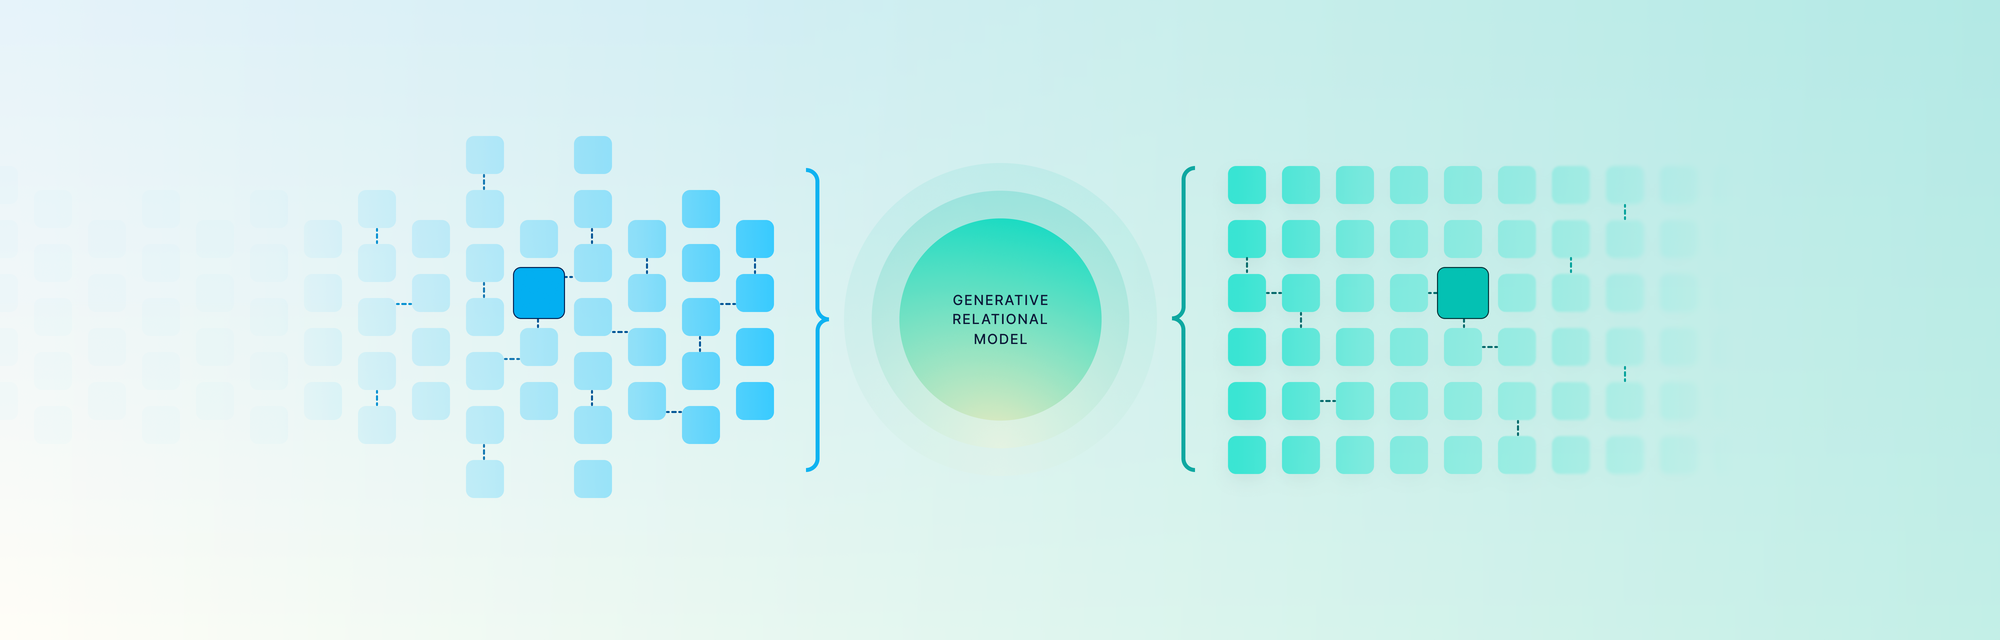
At DataCebo, instead of relying on a general-purpose foundation model, we provide enterprises with a software stack, known as The Synthetic data vault (or SDV), that trains generative models directly on the company's own proprietary data. The resulting model, a “Generative Relational Model,” becomes a reusable AI asset for the company, and can be used across a variety of downstream applications. In this article, we describe the initial deployment of the commercial version of software (called SDV Enterprise, after the most impactful outcome these models produce — synthetic data). We share how enterprises have used SDV Enterprise, what challenges have emerged, and how we are now scaling this ability enterprise-wide. Today we’re launching a major new release, SDV 2.0, which enables enterprises to build their own generative relational models through a fully automated workflow, with minimal manual effort.
Generative models for enterprise relational data
In 2024, we launched SDV Enterprise, a commercial version of the SDV Community that allows enterprises to build their own generative models. Simply provide the SDV with a representative subset of an enterprise database, and the software trains a generative AI model that quickly learns that data's statistical patterns and relationships. The algorithms that power the SDV Community were originally developed at MIT, and then scaled to work with any number of tables and any relational depth.
Unlike large language models, these models are easy to train: They require only a subset of the data for training, and can train in minutes rather than weeks, often on a standard CPU machine. After training, the resulting generative model belongs to the enterprise. For many of our early customers, the generative AI model that trained on their data became a reusable AI asset for their enterprise. Like other generative models designed for language and vision, these models were able to faithfully generate highly realistic synthetic databases. This ability to create realistic synthetic databases became the first application for these models.
Generative relational models can produce entirely synthetic databases - and this became their first use case
These generative relational models provided enterprises with the ability to create realistic synthetic databases. Because a generative relational model has learned the statistical patterns, data structure, relationships, context, and business rules embedded in the data and spanning multiple tables within a database, it can generate entirely new synthetic records while preserving those important characteristics. It can generate billions of new records on demand, and create realistic synthetic databases at virtually any scale.
The resulting synthetic databases transformed the process of provisioning the compliant, secure, and representative data software developers need to test applications in lower environments. Before SDV Enterprise, our customers had to copy, mask, and transform production databases through complex, infrastructure-heavy test data management workflows. With SDV Enterprise, our customers now train a generative relational model and create synthetic databases. This data can then be used for regression testing, performance testing, generation of edge case scenarios. One of the first documented uses was at ING, which successfully built a generative relational model and created synthetic data to test SEPA payment applications. Within a year, ING was using synthetic data created through this process for 20 different applications across different departments and business units.
These synthetic databases also found a very powerful application in architecting database infrastructure. Teams fine tuned their database configurations using heuristics or rules proposed by the database vendor. With synthetic databases they can try various configurations without distributing production databases.
What we've learned from enterprise deployments
After our launch and early successes, customers from industries including financial services, healthcare, and consumer goods began using SDV Enterprise. Working with these customers made us aware of special complexities inherent to enterprise relational data. To ensure enterprise wide development of generative models for this kind of data, we must address these complexities natively.
Below, we summarize five complexities that these generative models must be able to handle.
1. Context embedded in data values. In enterprise relational data, context is frequently embedded in the values of a particular data type or column. This context dictates the data's format and structure, and how it correlates with other columns. Different data types also have unique rules and storage procedures. To be effective, synthetic data must preserve this context. For example, ID columns may carry important business information and rules; any generated ID column data must contain this information and respect these rules. We present these interesting properties of ID columns in this video. To address this, we enabled flexible data processing. Users can specify their context and rules, and SDV embeds this information when training the model. We called this ability the "Programmable Synthetic Data Stack," because users are programming the SDV's generative models by providing these inputs.
2. Complex relationships across enterprise Data. Similarly, virtually all enterprise databases have composite keys that connect tables. These keys and connections take many forms. Add to this polymorphic relationships and reference tables, the numerous rules governed by the implicit logic of how data is stored, and the fact that many enterprise databases are intentionally split across teams, but maintain implicit connections. It's not possible to bring all of this data together to train a generative model. Instead, independently trained models must recognize these connections, and generate data that remains consistent across them.
3. Business rules in enterprise relational data. As people use systems, products, and services, business logic governs how data is created. For example, in a financial services database, a user must have a savings account before they can have a credit card. Applications rely on these deterministic rules to process data. Generative models must learn these rules and produce records that follow them, while also maintaining the database structure and statistical correlations. If they don't follow these rules, generated data may be statistically valid, but useless in practice. We call these rules constraints, and w e allow users to provide this business logic when training the model, an approach we call Constraint-Augmented Generation.
4. Representative training data selection. Another common question asks what data should be used to train the model. Some assume it's best or necessary to train on all of an enterprise's data (which can run to many terabytes) or to use an entire production database, which is rarely feasible in practice. Fortunately, many studies have shown that carefully selected representative subsets can effectively capture the statistical properties of much larger structured datasets. The challenge then becomes selecting that subset: How do we avoid introducing bias? How do we ensure important context is not missed, especially when data spans many tables? In addition, the training algorithms must be designed to recognize that they are learning from a representative subset rather than the complete database.
5. Task-oriented data generation. The promise of generative models is that they can recreate realistic data. But randomly sampling data from hundreds of tables may not produce the low-frequency events, edge cases, and boundary conditions a user needs. Instead, data generation should respond to the user's specific requirements.
For example, a user may ask for data representing 10 customers from Ohio who all own Audis and have savings account balances greater than $1 million. Regardless of how frequently these records occurred in the original dataset, the software must generate them. Although the user specifies values for only three variables—State = Ohio, Car Owned = Audi, and Savings Account Balance > $1 million—the model must generate values for the thousands of remaining variables, and return a complete dataset.If this requested combination never existed in the original training data, the model must extrapolate while informing the user that it is doing so.
The traditional approach to this problem is to generate a large volume of data and repeatedly filter out records that do not satisfy the requested conditions until enough matching records remain. This approach does not scale.
SDV Enterprise now supports targeted sampling, out-of-range sampling, and several other sampling approaches that respond to the user's specific task.
Over the past two years, we evolved SDV to address all of these complexities, resulting in what we call the Programmable Synthetic Data Vault. The idea is simple: users can program the behavior of their generative model through configurations and settings. When we upgraded SDV to SDV 1.0, we deliberately built it to accept user input, anticipating that enterprise data would present even more complexities that we had not yet encountered. This evolution led one customer to say, "The product is evolving at a frantic pace."
SDV 2.0: From programmability to automation
After we gave users the ability to specify constraints, data patterns, and complex structures through metadata, settings, and configurations, they began asking: How do we do this at enterprise scale? The generative models were producing highly realistic, valid, and task-specific data, and customers were experiencing the benefits of the new workflows these models enabled. They were ready to do even more. (One of our customers, a Fortune 100 bank, wanted to make SDV Enterprise its global synthetic data standard.)
These conversations changed how we thought about enterprise generative AI. Programmability worked well when users knew the business rules, data formats, and relationships they wanted to specify. But as our customers pointed out, this level of control is rarely possible at enterprise scale.
First, enterprise databases are enormous, and often contain hundreds of tables and thousands of columns. Many organizations are simply not aware of all of the embedded context, business rules, or complex relationships contained in their own data. Second, enterprise data is notoriously underdocumented, with missing lineages and incomplete information about relationships. A common example is the lack of foreign key information. When data spans multiple departments, these connections become even muddier.
This line of thinking led us to our latest evolution: automation.
It became clear that—if our goal was for users to be able to easily build generative models for any enterprise database—--the generative models needed to be able to be trained automatically, without depending so much on human input. Thus, we created features for automatic detection of constraints, business rules, data formats, and database structure (including primary keys, foreign keys, and composite keys). This brought us to SDV 2.0: a significant milestone for our product. Our users no longer have to work to train a generative relational model using SDV Enterprise. They can point the product to a database or a set of files, and SDV Enterprise will:
- Automatically detect the structure and connections (including primary, foreign and composite keys and polymorphic relationships);
- Automatically detect all constraints resulting from business rules;
- Automatically detect the formats and context embedded in the data values;
- Create a valid representative minimal training dataset;
- Trains the model by tuning itself for optimal performance;
- Automatically sample task-specific data.
Platform automation maturity model
Our experiences building and deploying SDV Enterprise also led us to a broader observation. With the first generation of our product, we proved that generative models can faithfully recreate enterprise relational data. Working with customers across industries then showed us that realistic data generation alone is not sufficient: To become reusable AI assets within an enterprise, these models must understand context, business rules, complex relationships, representative training data, and user intent, while automating as much of this process as possible.
Here, we lay out a four-level categorization scheme for platforms that can help enterprises build generative relational models from their databases, based on their maturity. These four levels do not reflect the quality of the underlying generative model. Instead, they describe how much enterprise data complexity a platform can handle, and how much manual effort is required from users to make it work.
Level 1: Platforms that handle only single-table and simple data structures
These platforms work only with data of limited scale and complexity, and clearly communicate this. For example, a platform at this level may state that it supports only single-table data. Another may support simple and commonly seen structures—for example, two tables with a one-to-many relationship, such as one customer table and one transactions table. When presented with many tables, these platforms typically resort to anonymizing PII, adding noise to the original data (non-PII values), performing column-by-column transformations, and using a number of other techniques to create “synthetic data.”
Level 2: Platforms that require pre- and post-processing
These platforms have core AI algorithms that can model a single table. For multi-table data, they require preparation of the data, so that they can handle more complex structures. For a number of other requirements, they also require users to perform pre-processing and post-processing.
Pre-processing (also sometimes called "feature engineering") typically creates an ETL pipeline. The pre-processed data is then modeled, and the samples generated from the models are post-processed to recreate the data in its original shape.
Because this strategy requires numerous pre-processing and post-processing techniques—as well as scripts and ongoing maintenance—it is not scalable at an enterprise level, even if significant support is offered.
Level 3: Platforms that handle enterprise complexity but require user configuration
These platforms are designed to handle the complexity inherent in enterprise data, as described in the previous section. They expose a number of settings that users can configure based on their data. These settings range from specifying metadata (which can be extracted from the schema), to defining regex formats for ID columns, to selecting the functionality the platform provides to address the various complexities. While the platform itself can address these complexities, the user is responsible for directing it by configuring its settings.
Level 4: Platforms that automatically learn the configuration from the data
These platforms are a step up from Level 3 because they no longer require users to specify settings or annotate columns with specific structures. Instead, they have additional AI capabilities that learn directly from the raw data itself. For example, these platforms can learn the regex patterns of ID columns, detect business logic, identify relationships between tables (such as composite keys, foreign keys, and primary keys), and recognize when a particular column encodes significant context. These platforms come closest to fully automated synthetic data generation.